Conversation

take me to wikipedia country
sierra
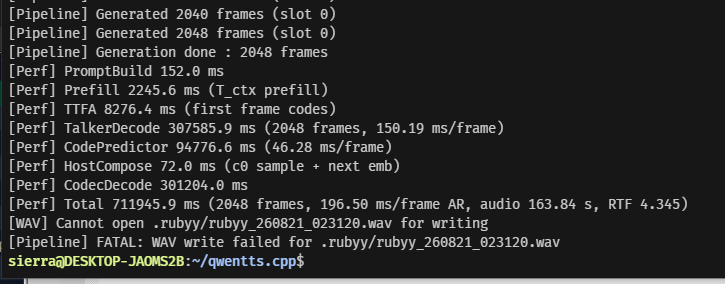
this shit uses my entire computer to do nothing for 20 hours fuck this shit
 0
 0
 0

@sierra you’re during vulkan inference and not cpu inference right?
2
0
0
@sierra it generates in real time for me and im on integrated graphics
1
0
0
Edited 24 days ago
@sierra cuda is probably the best option then. you could try the smaller Q4_K_M model quantization in the huggingface repo. how long is your reference audio? for decent results it doesn’t need to be longer than a minute
1
0
0
Edited 24 days ago
@sierra upload the file let me hear also i usually do 30s-1m so maybe more reference will make it better but also maybe slower
1
0
0
@sierra yeah i tried its okayish for me i think longer and more clear reference would make it better
1
0
0